


But are these <http://epoch.ai> assessments real numbers that mean anything? And how could we tell? The apparent slowdown in LLM improvement is exactly what you would expect if the LLMs are at base just emulating internet s***posters. But if the compression = true understanding crowd is right, the scale may well be measuring the wrong thing…
Whether we are on the road to AGI hinges on an unsettled question: What are LLMs?
If they are sophisticated mimics of human conversation, plateauing capability scores make sense and the AGI story is hype.
If compression-into-weights actually recovers, by seeking minimum Kolmogorov complexity, the true generating structure of deep thought that humans carry on before they then produce their jittery and very human text, then maybe it is time to start planning to welcome our potential AGI overlords.
Paul Kedrosky reprints a graph he has had on his mind for some time:
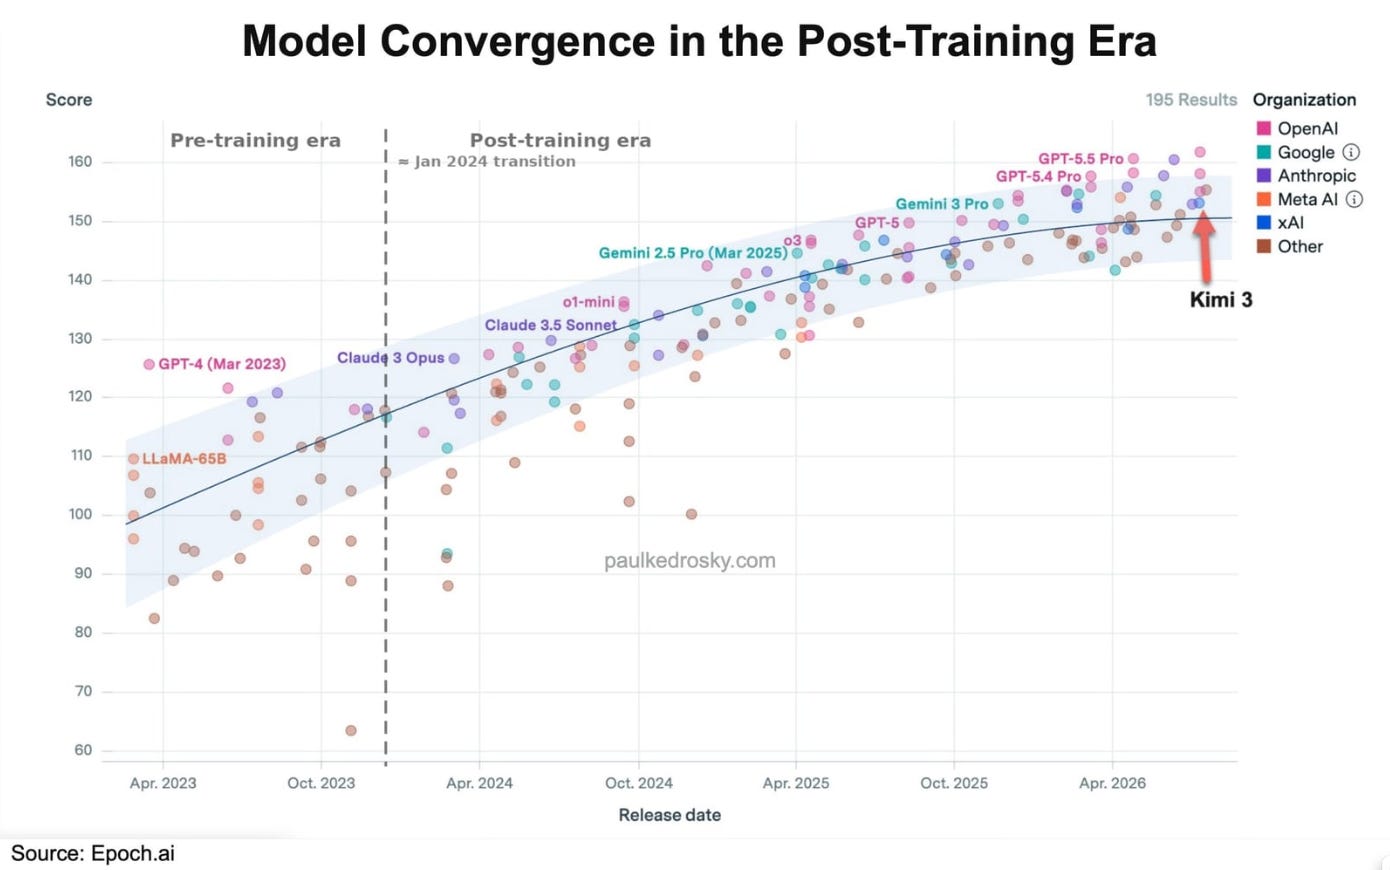
Paul Kedrosky: Kimi, Model Convergence, & the Post-Training Era <https://paulkedrosky.com/kimi-model-convergence-and-the-post-training-era/>: ‘Moonshot’s Kimi K3 model has people over-excited, as if some trend has been broken, but they’re wrong…. We exited the pre-training era and became more reliant on post-training, like RLHF. In the post-training era, successive releases deliver smaller capability gains, fewer durable outliers, and less defensible technical differentiation…. Te value of each incremental model release (ignoring harnesses) is falling, even if production costs aren’t…. Model prices compress…. Inference becomes increasingly commoditized…. Frontier development becomes harder to monetize…. Value shifts away from the base model…
The big joker in his analysis of course is this: What exactly is on the vertical axis of these scores from <http://epoch.ai>? Why should we care? What difference does it really make?
If you believe, as I do, that LLMs are going around Robin Hood’s barn, yeah, because they’re “emulations of the typical internet shit poster”, then frantically corrected to sanity by RLHF and such, this is as expected. You are trying to faithfully emulate what the person whose ghost you are pantomiming said, so it is really hard to get smarter than them. After a point, the better classification of what human conversations are “close” to the one the LLM is having is not worth much at all.
That leaves the use of MAMLMs for very big-data, very high-dimension, very flexible-function classification. True deep magic appears to have emerged with respect to programming here—perhaps. And there is no doubt that other superuse cases will emerge at a rate and with an impact I cannot forecast.
There are, however, people who say that the frontier model-builders are closing in on true “AGI”, true “Artificial General Intelligence”, something that, surveying across all of the subdomains of cognition and averaging, is human-level albeit not human-like.
When I ask them how it can possibly do this, they are either (a) silent, or (b) they say compression. They say that the “fuzzy .jpeg of the web” line of Ted Chiang’s gets it exactly backwards. What the LLM does as it compresses its training data into the weights of its virtual emulation of a neural network is to, in some way, generalize. What it loses is not fuzziness, but the jitteryness of individual human error. Thus it gains the wisdom of crowds à la Sean Trott <https://seantrott.substack.com/p/gpt-4-sometimes-captures-the-wisdom>: it says not what the human did in the closest conversation, but what each of the humans would have said in all of the close conversations if each had had knowledge of what all the other humans in similar conversations were saying and thinking.
What that does is produce structural recovery: true knowledge of what is going on, in a context where it is the humans who each have only a fuzzy .jpeg view of the surface appearance of things, or at least of relationships between words.
If they are right, then this <https://epoch.ai/eci?subset-view=graph&subset-tab=Software+engineering&view=graph&tab=release-date> Capability Index is fundamentally wrong, and misleading us.
Um—maybe?
How could I figure this out? Damned if I know. Some thoughts below:
As best as I can figure it out, the pro-compression-induces-true-knowledge line is pushed by people like Ilya Sutskever <https://www.youtube.com/watch?v=AKMuA_TVz3A> <https://www.ted.com/talks/ilya_sutskever_the_exciting_perilous_journey_toward_agi> and Jack Rae <https://www.youtube.com/watch?v=dO4TPJkeaaU>: Rae, especially, sees LLM training as computing the probability distribution that lets you transmit all of human knowledge over a low-bandwidth channel in the fewest bits, reconstructing the generating distribution rather than making a blurry copy, and so doing something much much more than pantomiming the nearest conversation internet s***poster. And Yuzhen Huang, Jinghan Zhang, Zifei Shan, & Junxian He argue that compression is indeed the essence of what LLMs are doing <https://arxiv.org/abs/2404.09937>.
And then there comes is the argumentative jump that I cannot quite follow: that the minimum-bit compression of the conversation generating function with the individual human jitteriness cleared out is what AGI is, for, in Ted Chiang’s terms it is a fact that “the greatest degree of compression can [only] be achieved by understanding the text…” <https://www.newyorker.com/tech/annals-of-technology/chatgpt-is-a-blurry-jpeg-of-the-web>.
Thus the core move is this: successful emulation requires minimum Kolmogorov complexity, which forces a world model. The only way to keep driving LLM loss down is to “learn” and then internally simulate and understand the processes that generated the text: physics, arithmetic, theory of mind, causal structure. Pushing compression far enough is then not analogous to intelligence; it is the operational definition of it. The model recovers as its object not an internet s***poster but rather the latent structure of cognition.
But Ted Chiang then, as I understand him, then says: the model-builders do not dare set temperature=0 because without human-like jitteriness added, the compressed version fails to convince us that it is thinking. Point. François Chollet <https://arxiv.org/abs/1911.01547> reinforces the anti-argument with his claim that intelligence is skill-acquisition efficiency on genuinely novel tasks, and draws a sharp distinction between models that look intelligent on benchmarks that are in the hyperplane of its training data and yet have near-zero generalization power. And Gary Marcus declares victory for the “scale is not all you need” crowd:
Gary Marcus: Scale Is Not All You Need <https://garymarcus.substack.com/p/breaking-news-scale-is-all-you-need>: ‘Altman claimed that “the intelligence of an AI model roughly equals the log of the resources used to train and run it…"… He bet the entire company on this notion. He was wrong…. Let’s bring in the cognitive scientists, and stop fantasizing that data and compute will solve all our problems. The time for neurosymbolic AI and world models and causality is now…
I am, in general, a bear on MAMLMs and a superbear on the usefulness of unharnessed LLMs: stochastic parrotage enables natural-language interfaces, which are wonderful. Full stop.
The thing that keeps me from being confident in my bearishness on MAMLMs in general is this: The genuine open frontier is not chat but MAMLMs used in other big-data, high-dimensional, flexible-function classification—like programming, where true deep magic has apparently emerged from Claude Code’s harness. Yes, writing code is a domain where surface prediction and correct world-modeling are very very close—programs either work or don’t, for there is no underlying reality to which the incantations in their correct form point. If compression is producing real generalization anywhere, that would be the cleanest place to see it.
And are there other similar domains where true deep magic is possible as well? How common are they? Where are they? Or is computer code the only domain where getting the symbols right invokes the reality directly?
So I guess the bottom line is this: right now um—maybe? is still the only sensible answer we can give.
"Yes, writing code is a domain where surface prediction and correct world-modeling are very very close—programs either work or don’t, for there is no underlying reality to which the incantations in their correct form point."
I am a life-long professional software developer. I am under continuous, albeit gentle (no leaderboards) pressure to make use of LLM coding assistance, both chat-based and agentic. I have the benefit of a wide choice of models and professional training from the vendors of these models. I am trying to reserve judgment on the usefulness of LLMs for programming, but the only reason is the proliferation of Silicon Valley programmers telling me how good it is. To be clear, I am not just talking about the "hamburger" model of Kapoor and Narayanan (https://www.normaltech.ai/p/why-ai-hasnt-replaced-software-engineers) - although they are right. In my observation, LLMs are only moderately useful at shrinking the "execute" patty, never mind the bun.
You have (inadvertently) identified what may be the problem: there absolutely is an underlying reference reality for most of the software that makes a difference in your life, and if you fuck that up, then you, too, will be fucked. We are not close to having an LLM that you want to have writing your bank's book-keeping systems, or your hospital's life support systems, or your railroads scheduling system, or basically any other software system of any real importance. I can rely on LLMs to manipulate data ("this .csv file represents a volatility surface in the format blah blah blah, this other file represents a volatility surface in format lorum ipsum, please reformat the .csv file to match the lorum ipsum format.") Using an LLM to write the first cut of a well-known or easily defined algorithm ("please write a function to find the nearest correlation matrix to a given matrix using the algorithm of Higham and Strabic") and it will usually produce a reasonable first cut that is arguably faster than typing in myself. Asking an LLM to find a bug in a complex system will generate suggestions; almost all are wrong and usually none are right. It is doubtful that the cases when it finds a right answer pay for the cost of evaluating the rest. Asking an LLM for a meaningful functional change, well you might as well trying flying to the moon by flapping your arms.
My point is that LLMs work best, when they work at all, on the kind of software that is written by Silicon Valley software developers, where "move fast and break things" is highly prized and the consequences of an error are not too serious. This is also the sort of software written by "part time" programmers, who just want a nice plot of the latest Fed data. But it doesn't represent much of the software that makes modern life possible.
Another domain would be mathematics. The Xena - Mathematicians learning Lean by doing blog points out that LLMs can be useful in translating mathematics into Lean, a theorem proving language where either the theorem compiles and is correct or it fails to compile and is incorrect. It requires a mathematician to check the Lean to verify that it is actually proving the theorem and not something sort of similar. It also needs the user to verify that it doesn't invoke anything that might delete all of one's files. Apparently, LLMs are also pretty good at finding counterexamples.
Like programming, mathematics requires precise statements, has a form of underlying truth and is highly regular in its use of language. "Not for us rose-fingers, the riches of the Homeric language. Mathematical formulae are the children of poverty."
One can see how LLMs would have problems with legal problems since the law and legal system have been developed to deal with the ambiguity of language. Our current Supreme Court has based numerous decisions on novel interpretations of what was once generally accepted language.